
AI systems add concerns that ordinary application architecture does not remove: non-deterministic output, context management, model and data drift, evaluation, and human review. Those concerns do not require one universal architecture. They change which boundaries are useful.
The patterns below are alternatives for different constraints. A small product may keep context inside a monolith. A system with several models and data sources may need a separate context pipeline. A high-risk decision may require an explicit human gate. The choice follows the operating conditions, not a maturity ladder.
Each section describes the structure, when it fits and what it costs to operate. The broader AI-first development principles explain how context and evidence connect across those choices.
The context-aware monolith
The core problem: Your AI needs context. Without it, interactions become disjointed, repetitive, and frankly, dumb. As explained by experts in AI usability and testing (like Frank Spillers or the folks at testRigor), understanding the ‘who, what, where, when, why’ is crucial for AI to provide genuinely useful responses rather than generic guesses. But when you’re building a simpler application – maybe a chatbot MVP or a focused content generator – jumping straight into complex microservice architectures for context management feels like overkill. How do you embed essential context awareness from day one without over-engineering?
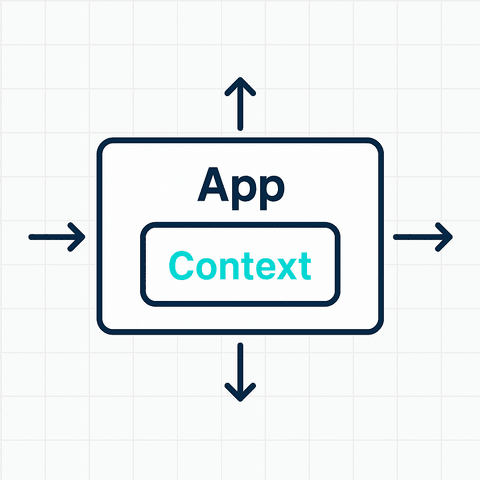
The pattern – integrate context internally: The Context-Aware Monolith tackles this head-on. Instead of building a separate, complex pipeline for context, you integrate context management directly within the main application logic. Think of it as giving your monolith a dedicated ‘memory’. The application itself becomes responsible for capturing, storing (perhaps in a dedicated internal module, class, or specific database tables), and retrieving the necessary context (like user history, session data, previous prompts/outputs) needed for each AI interaction. This aligns with the fundamental need for AI systems to have memory or “cognition” to be effective.
Why start here?
- Keep it simple: It’s far easier to implement and manage for smaller projects or initial versions (MVPs). Less moving parts means faster development initially.
- Lower latency (at first): Context is immediately available within the application’s process, potentially reducing the overhead of external service calls.
- Unified logic: Development, core features, and context management live together, simplifying the initial codebase and debugging.
Warning: This pattern is best suited for applications with a relatively limited scope and scale. As complexity grows, the tight coupling between application logic and context management can become a bottleneck. Be prepared to evolve to more decoupled patterns (like the Context Pipeline below) as your needs expand.
The decoupled context pipeline
The problem it solves: Your AI system needs to handle complex context from multiple sources (user input, databases, external APIs), process it, enrich it, and make it consistently available to various AI models or agents. The context-aware monolith is starting to creak.
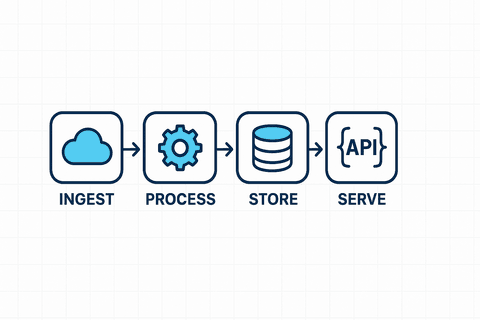
How it works: You build a dedicated, separate service or pipeline whose sole job is context management. This pipeline ingests raw context, processes it (e.g., embedding generation, summarization, entity extraction), stores it effectively (vector databases are common here), and serves it up to the AI models when needed. This is the layer the framework calls context injection, and it is what lets teams achieve sustainable productivity gains.
Benefits:
- Scalability: Context processing can scale independently of the main application.
- Modularity: Easier to update or swap out context processing techniques.
- Reusability: The processed context can potentially serve multiple AI models or applications.
Implementation notes: Introduces more architectural complexity and potential latency compared to the monolith. Requires careful design of the pipeline stages and context storage.
The agentic feedback loop
The problem it solves: Your AI system needs to learn and adapt over time based on its own outputs or explicit user feedback. How do you build a system that isn’t static but continuously improves its performance or corrects its mistakes?
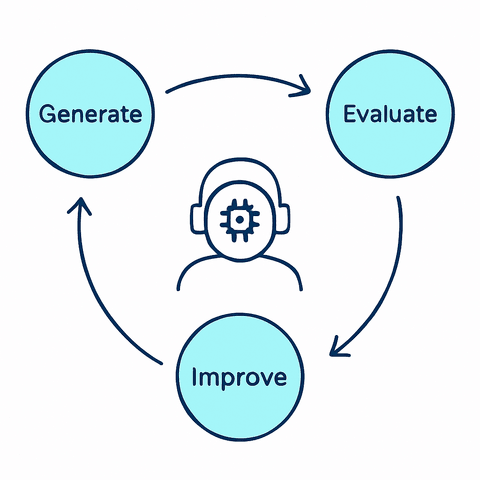
How it works: This pattern designs the system so that the AI’s output (or feedback on that output) is fed back into the system to modify future behavior. This could involve:
- Storing successful prompt/output pairs for few-shot learning.
- Using user ratings to fine-tune an underlying model.
- Having an AI agent analyze its own errors to generate corrective prompts.
Benefits:
- Self-improvement: The system can potentially get better over time without constant manual intervention.
- Adaptability: Can adjust to changing data patterns or user preferences.
- Resilience: May learn to recover from certain types of errors.
Implementation notes: Requires careful design to avoid unintended feedback loops or biases. Monitoring is crucial. Can be complex to implement and debug.
Stratified AI systems
The problem it solves: You want to leverage powerful, general-purpose foundation models (like GPT-4, Claude 3) but need to apply them to very specific tasks or domains without constantly fine-tuning the massive base model. How do you layer specialized intelligence on top of general capabilities?
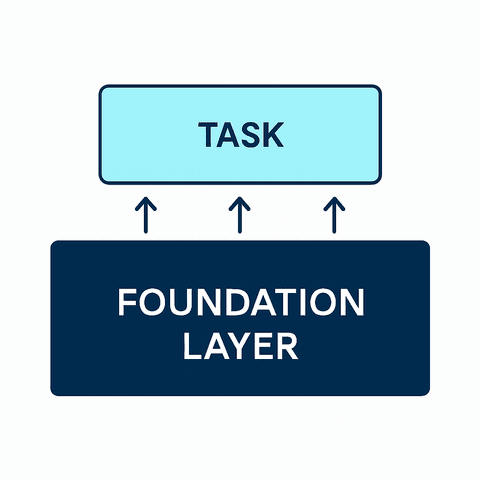
How it works: You create distinct architectural layers.
- Foundation layer: Houses the large, general-purpose AI model(s). Handles core language understanding, generation, or other broad capabilities.
- Application/task layer: Contains smaller, specialized models, prompt templates, business logic, and context specific to your application. This layer orchestrates calls to the foundation layer, adding the necessary task-specific context and interpreting the results. This implements the intent-driven architecture discussed in the AI-First Development Framework Guide.
Benefits:
- Reusability: Leverage powerful foundation models across multiple applications.
- Faster development: Focus application development on the specific task layer.
- Easier updates: Update foundation models with potentially less impact on application logic (though prompt engineering might need adjustments).
Implementation notes: Requires clear API design between layers. Managing prompts and context injection at the application layer becomes critical.
Human-in-the-loop orchestration
The problem it solves: Your AI system operates in a high-stakes domain (e.g., medical, financial) where errors are unacceptable, or it encounters situations with high ambiguity where AI alone cannot make a reliable decision. How do you blend AI automation with necessary human judgment?
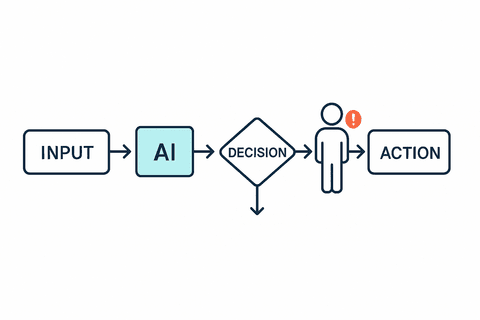
How it works: You explicitly design points in the workflow where human intervention is required or requested. This could be:
- AI flags low-confidence predictions for human review.
- A human must approve critical actions proposed by the AI.
- Users provide feedback that directly corrects or guides the AI’s next steps within the process.
- The system routes ambiguous cases to a human expert queue.
Benefits:
- Safety & reliability: Reduces the risk of critical errors in sensitive domains.
- Trust: Increases user and stakeholder trust in the system.
- Handling ambiguity: Leverages human judgment for situations AI struggles with.
- Data generation: Human interactions can generate valuable data for future AI training.
Implementation notes: Requires designing efficient user interfaces for human interaction. Need to manage potential bottlenecks caused by human review times. Define clear criteria for when human intervention is triggered. This pattern aligns with the responsible use section of the framework.
Choosing a pattern
None of these five is a default. Each one trades an operating cost for a specific capability, and the cost is not abstract, it is the extra process you now run, the extra latency on every request, or the extra review step someone has to staff.
- The monolith costs almost nothing beyond the application itself, which is why it fits a project too small to justify anything else.
- The pipeline costs a second service to run, deploy and monitor, in exchange for context that scales independently of the main app.
- The feedback loop costs ongoing attention, unmonitored it can reinforce its own mistakes as easily as it corrects them.
- Stratified systems cost the API design between layers, but keep the foundation model swappable without touching application logic.
- Human-in-the-loop costs the slowest thing in the system, a person’s time, in exchange for a check that catches what no automated gate does.
Pick the pattern whose cost you can actually staff, not the one that sounds most sophisticated. Securing AI-generated code covers what to check once a pattern is running in production, and the AI-first development framework is where these choices connect to the rest of the loop, the context each pattern feeds and the evidence it has to produce.
You can download PAELLADOC to model the chosen architecture alongside its product decisions and verification evidence, or compare the agent tools it orchestrates before choosing an execution layer.
Frequently asked questions
Why do so many AI projects fail after the prototype?
Because teams treat AI systems like traditional software and guess their way through design. AI brings challenges ordinary architecture ignores: non-determinism, context decay, data drift. A prototype that looked promising becomes a tangle of technical debt nobody understands. The failure is usually structural, not bad luck. The system had no architecture built for the specific messiness of AI, so it could not survive past the demo.
What are the main AI architecture patterns?
This guide covers five battle-tested ones: the context-aware monolith, which keeps context inside the app for simpler projects; the decoupled context pipeline for scaling context handling; the agentic feedback loop, where outputs and feedback improve future behaviour; stratified systems that layer specialised logic on top of foundation models; and human-in-the-loop orchestration for high-stakes decisions. Most real systems combine several as they grow.
How do you choose the right AI architecture pattern?
Start from your project’s scale, complexity and risk, not from the most sophisticated option. A focused MVP may only need context handled inside the application; a system serving many models needs a dedicated context pipeline; high-stakes domains need explicit human review points. The constant across all of them is that deliberate structure, rather than improvised design, is what keeps an AI system alive past launch.
What does each pattern cost to run in production?
The monolith costs the least, since there is no extra service to operate. Every other pattern trades that simplicity for a specific capability: a pipeline costs a service to deploy and monitor, a feedback loop costs ongoing attention so it does not reinforce its own mistakes, stratified layers cost the API design between them, and human-in-the-loop costs someone’s time on every case it routes to a person. None of that cost is optional once you pick the pattern, only visible sooner or later.
Which pattern should I start with?
Start with the monolith unless you already know why it will not hold: too many data sources to keep in one process, a domain where an unmonitored mistake compounds, or a decision no automated check should make alone. Move to the next pattern when the current one is visibly the bottleneck, not before.